VIDRAFT Takes #1 on BRIGHT, the New Reasoning-Retrieval Leaderboard on Hugging Face
aimachinelearningsearchrag
TL;DR
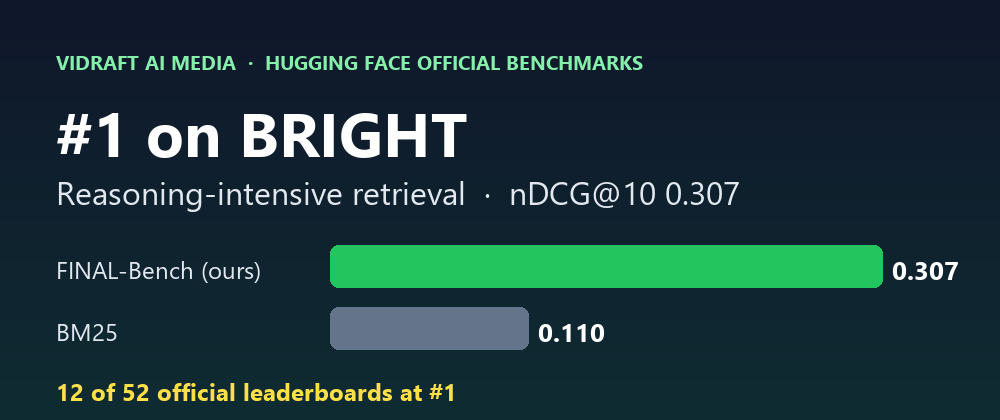
BRIGHT, a reasoning-intensive retrieval benchmark, is a new addition to the Hugging Face official benchmark leaderboards. VIDRAFT's FINAL-Bench/Darwin-BRIGHT-Retriever is #1 with 0.307 nDCG@10. Second place, the classic BM25 keyword search, scores 0.11. With this result, VIDRAFT is #1 on 12 of the 52 Hugging Face official benchmark leaderboards.
- Benchmark: huggingface.co/datasets/mteb/BRIGHT
- Our entry: huggingface.co/FINAL-Bench/Darwin-BRIGHT-Retriever
What is reasoning retrieval?
Ordinary search finds documents that contain the words in the question. BRIGHT is built so that this does not work: the question and the right document share almost no words. To find the document, the system must first work out what the question needs.
An example:
| Question | Keyword search | Reasoning retrieval |
|---|---|---|
| "I feel like throwing up and my stomach is cramping." | Matches "throw up" and "stomach", returns unrelated pages | Infers "this looks like food poisoning", returns food-poisoning first aid |
BRIGHT covers questions of this kind from areas such as science, programming, economics and math, where the useful document explains a concept the question never names.
How hard is it?
Very hard. The score is nDCG@10, which rewards putting the right documents at the top of the first ten results. A perfect system would score 1.0.
| Rank | System | nDCG@10 |
|---|---|---|
| 1 | FINAL-Bench/Darwin-BRIGHT-Retriever | 0.307 |
| 2 | BM25 | 0.11 |
Even at #1, the score is about 31 out of 100. That is 2.8 times the keyword baseline, and it shows how much room this task still has. The result is registered on the Hugging Face leaderboard with the note "Obtained using MTEB", the standard embedding evaluation toolkit.
Why does this matter for RAG?
Most retrieval-augmented generation (RAG) systems fail before the language model sees anything: the retriever returns the wrong documents. Real user questions often describe a symptom, an error message or a situation, not the name of the concept that solves it. A retriever that reasons about the question first can find the answer that a keyword or plain similarity search misses.
12 of 52
The Hugging Face official benchmark leaderboards now cover 52 benchmarks. VIDRAFT's FINAL-Bench organization is #1 on 12 of them, including AIME 2026 and HMMT 2026 (100%), GPQA Diamond (94.44), MMLU-Pro (88.12), MMMU-Pro (79.48), LEXam (68.94), ExtractBench (90.29), IFStruct (98.95), MDPBench (83.65) and now BRIGHT (0.307). These are self-reported scores, as on every Hugging Face benchmark leaderboard.
FAQ
What is BRIGHT? A retrieval benchmark where the query and the relevant document share few words, so finding the document needs reasoning about the query.
What score did VIDRAFT get? 0.307 nDCG@10, #1 on the Hugging Face BRIGHT leaderboard. BM25 is second with 0.11.
Why is the top score only about 31? Because the task is hard by design. Keyword overlap, the signal most search systems rely on, is removed.
Is the score verified by Hugging Face? No. Like all entries on these leaderboards, it is self-reported by the publisher. It was obtained with MTEB.
How many leaderboards does VIDRAFT lead? 12 of the 52 Hugging Face official benchmark leaderboards.
Links
- BRIGHT benchmark: mteb/BRIGHT
- Our entry: FINAL-Bench/Darwin-BRIGHT-Retriever
- VIDRAFT: vidraft.net